足ることを知らず

Data Science, global business, management and MBA

Communication and Crisis Management in the Age of AI

AI時代のCrisis Management

MITの「AI時代のCrisis Management」という授業を受けた。

危機というと、まず技術的な問題や事業への直接的な影響に目が向きがちだ。システムを復旧させる、業務を継続させる、被害を最小限にする。もちろん、どれも必要。

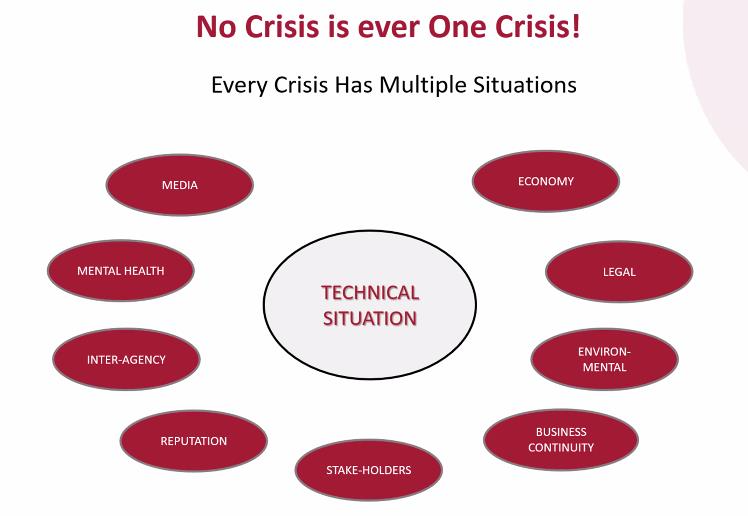
ただ、授業で示された図には、技術的な状況を囲むように、Legal、Media、Economy、Business Continuity、Reputation、Stakeholders、Mental Healthなどが並んでいた。


危機は一つではない。

技術的な問題が起きれば、それと同時に、従業員や顧客への説明、法的な判断、世論や評判への対応など、複数の課題が動き出す。技術チームがよい仕事をしても、コミュニケーションがうまくいかなければ、組織全体の対応が失敗と見なされることもある。

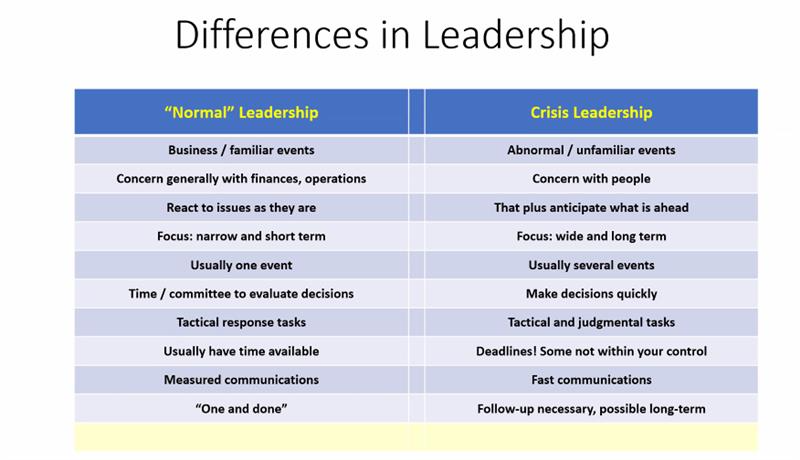
危機時のリーダーシップは、平時のリーダーシップとは違う。


慣れた状況ではなく、予想外の状況。
一つずつではなく、複数の出来事が同時に起きる。
検討に時間をかけるのではなく、限られた時間で判断する。
一度伝えれば終わりではなく、その後も状況に応じて伝え続ける。

つまり、何を決めるかだけでなく、どの順番で決めるのか、誰に何を伝えるのか、どうフォローするのかが問われる。

学び①:危機時のコミュニケーションは、対応の一部である

技術的な対応とコミュニケーションを別々に考えてはいけない。
復旧や封じ込めが進んでいても、関係者が状況を理解できず、不安や不信が広がれば、コミュニケーションそのものが新しい危機になってしまう。

だから、危機対応では「何が起きたか」だけでなく、「誰が影響を受けているか」「それぞれが何を知りたいか」を見なければならない。全てのステークホルダーに、同じ情報を同じタイミングで届ければよい、ということでもない。必要な情報は相手によって違う。

学び②:信頼は、専門性だけでは築けない

授業で紹介された信頼の構成要素の図では、Expertise & Competence、Honesty & Openness、Commitment & Devotion、Empathy & Caringのうち、Empathy & Caringが約52%を占めていた。

数字そのものをどこまで一般化できるかはさておき、この図が示すメッセージは分かりやすい。専門性や正確さは重要だが、影響を受けた人に関心を持ち、その状況を理解しようとする姿勢がなければ、信頼にはつながりにくい。

Deepwater Horizon事故後のCEOの発言も紹介された。被害を受けた人々の生活が大きく損なわれているなかで、「自分の人生を取り戻したい」という趣旨の発言が出た。本人の意図とは別に、聞き手には「この人は自分のことを考えている」と受け取られてしまった。

言葉の正しさだけではなく、その場で誰の視点に立って話しているのかが問われる。

学び③:AIが発信を速くするほど、人間の判断が重要になる

AIを使えば、情報を整理し、メッセージの草案を作り、発信までの時間を短縮できる。危機対応において、スピードは大きな助けになるはずだ。

一方で、速く発信するだけでは足りない。誰に向けた言葉なのか。相手はどんな影響を受けているのか。何をまだ確認できていないのか。どの言い方が、相手にどう受け取られるのか。

こうした判断をしないままAIで文章を整えると、形式は整っていても、相手の状況に向き合っていないメッセージになり得る。AIが作る速度と、人間が担う判断の質。その両方が必要になる。

Crisis Managementは、危機が起きた後に対応チームを立ち上げればよい、というものではない。平時から、誰が判断し、誰が伝え、誰がフォローするのかを考えておくこと。関係者の懸念を把握し、信頼を築いておくこと。そうした準備が、危機時の意思決定とコミュニケーションを支える。

AIによって、情報を作ることも、届けることも速くなる。だからこそ、相手を理解し、影響を引き受け、信頼を保つことの重みは、これまで以上に増していくのだと思う。

When we think about a crisis, it is easy to focus first on the technical problem or its direct impact on the business: restoring a system, keeping operations running, or limiting the damage. All of that matters.

But one of the slides showed a technical situation surrounded by other issues: legal, media, economic, business continuity, reputation, stakeholders, and mental health.

A crisis is never just one crisis.

A technical incident can trigger several other challenges at once: communicating with employees and customers, making legal decisions, and responding to public scrutiny. Even when the technical team does its job well, poor communication can make the organization’s entire response feel like a failure.

Leadership during a crisis is different from leadership in normal circumstances.

The situation is unfamiliar. Several events may unfold at once. Decisions have to be made quickly, often with incomplete information. And communication is not a one-time announcement; it requires continued updates and follow-through.

In other words, it is not only about what to decide. It is also about the order in which decisions are made, who needs to hear what, and how the organization follows up.

Lesson 1: Communication is part of the crisis response

Technical response and communication cannot be treated as separate workstreams. A team may be making progress on containment or recovery, but if people cannot understand what is happening, uncertainty and distrust can grow. Communication can become a crisis of its own.

That means asking not only “What happened?” but also “Who is affected?” and “What does each group need to know?” Different stakeholders may need different information, at different times.

Lesson 2: Expertise alone does not build trust

One slide broke trust and credibility into four components: Expertise & Competence, Honesty & Openness, Commitment & Devotion, and Empathy & Caring. Empathy and caring accounted for about 52%.

The exact percentages may not apply universally, but the message is clear. Expertise and accuracy matter. Yet they may not build trust if people do not feel that the organization understands or cares about what they are experiencing.

The instructor also discussed BP CEO Tony Hayward’s remarks after the Deepwater Horizon disaster. At a time when many people were suffering, Hayward said he wanted his life back. Whatever he intended, the comment shifted attention to his own hardship. It was received as a sign that he was focused on himself rather than on those affected.

The words themselves matter, but so does the perspective they reveal: whose situation are you centered on when you speak?

Lesson 3: The faster AI makes communication, the more human judgment matters

AI can organize information, draft messages, and help reduce the time it takes to communicate. In a crisis, that speed can be valuable.

But speed alone is not enough. Who is the message for? What impact are they experiencing? What is still unknown? How might they interpret the language being used?

If we use AI to polish a message without working through those questions, we may end up with something that sounds polished but does not show that we understand the people affected. AI can help us communicate faster; people still have to exercise judgment about what to say, to whom, and when.

Crisis management does not begin when an incident occurs and a response team is assembled. It also depends on the work done beforehand: clarifying who makes decisions, who communicates, and who follows up; understanding stakeholders’ concerns; and building trust before it is tested.

AI will make it faster to create and distribute information. That makes the human work of understanding others, taking responsibility for the impact of our actions, and maintaining trust even more important.


改めて感じるバランス型人財国家日本

攻守のバランスは、誰が取るべきか。

日米のリーダーを観察していて、ふと気づいたことがある。

アメリカのリーダーは、極端だ。

市場をこじ開ける「攻め」の人は、数字やガバナンスに驚くほど無関心になる。

一方で「守り」の人は、徹底して守りに徹する。

対して日本人は、攻めと守りのバランスが極めて美しい。

ブレーキとアクセルを、一人の人間が自然と踏み分ける。

しかし、これは個人の資質の差ではない。

組織が信じる「前提」の差だ。

アメリカ型は、モジュールである。

10倍の成長を狙い、一つの突出した強みを限界まで尖らせる。

欠陥や弱みは、別の専門家を当てて補完すればいい。

チーム全体で辻褄を合わせる設計思想だ。

日本型は、インテグラルである。

失敗を避け、調和を保つために、個人の内にブレーキを同居させる。

大事故は起きない。

だが、常識を破壊するような異能も生まれにくい。

バランスを、個人の内に求めるのか。

それとも、チームの組み合わせで作るのか。

優れたリーダーとは何か。

その答えの差は、個人の能力ではなく、組織の設計思想が生み出している。

英語翻訳(English Translation)

Where Does Balance Belong? The Architecture of Leadership

Observing American and Japanese leaders, I arrived at a realization.

American leaders are often polarized.

Those specialized in "offense"—driving deals and breaking open markets—can be surprisingly indifferent to governance and numbers.

Conversely, those in "defense" focus entirely on risk and control.

In contrast, Japanese leaders strike an exceptional balance between the two.

A single individual instinctively knows when to step on the accelerator and when to tap the brakes.

Yet, this is not a difference in personal capability.

It is a difference in the foundational assumptions of the organization.

The American model is modular.

Chasing 10x convex growth, it sharpens a single, exceptional strength to its absolute extreme.

Weaknesses do not need to be fixed by the individual; they are patched by another specialist.

Balance is engineered at the team level.

The Japanese model is integral.

To avoid fatal errors and preserve harmony, individuals internalize their own checks and balances.

Catastrophic failures rarely happen.

Yet, radical anomalies that break paradigms rarely emerge.

Do we demand balance within the individual?

Or do we construct balance through the composition of the team?

What defines a great leader?

The answer is shaped not by individual talent, but by the architectural design of the organization.

『昭和16年夏の敗戦』——日本は「間違った判断」をしたのではなく、「決められなかった」のではないか


書名: 『昭和16年夏の敗戦』
著者: 猪瀬直樹
出版年: 1983年(初出)/2010年(今回の中公文庫版)
ジャンル: 歴史ノンフィクション/組織論/意思決定
読了日: —
読書時間: —
ひとことで: 日本の敗戦を、情報不足や能力不足ではなく、「正しい分析があっても意思決定に結びつかない組織」の問題として読む本。

今回読んだ中公文庫版は2010年刊。もともとの単行本は1983年に刊行されている。日米開戦前、総力戦研究所に集められた若手エリートたちはシミュレーションの結果、日本の敗北を予測していた。それでも現実の日本は開戦へ進んだ、というのが本書の中心にある。

この本を一言でいうと

この本は、「なぜ日本は戦争に負けたのか」を説明する本というより、なぜ優秀な人間が十分な情報を持ち、かなり正確な未来予測までしていながら、組織としては反対の方向へ進んでしまうのかを問い直す本だと思った。

総力戦研究所の模擬内閣が出した結論は「日本必敗」だった。重要なのは、その予測が結果的に当たったこと以上に、予測する能力が存在したにもかかわらず、それが国家の意思決定を変えられなかったことだ。

つまり、問題は「頭が悪かった」ことではない。

わかっていたのに、決められなかった。

ここに、戦前の日本だけでは終わらない怖さがある。

なぜ今、この本を読んだのか

読みながら何度も、これは80年以上前の日本についてだけ書かれた本ではないと思った。

組織における合意形成、責任の所在、若手とベテランの役割、そしてリーダーが「変えられるもの」と「変えられないもの」をどう区別するか。

海外で生活したり、異なる文化の中で仕事をしたりすると、日本的な意思決定の特徴を逆に意識する場面がある。

特に感じるのは、日本ではしばしば、

「何を決めるべきか」

より先に、

「何なら全員が納得できるか」

を考えてしまうことだ。

それ自体は、平時には組織を円滑に運営する強みでもある。しかし、不確実性が高く、時間制約があり、誰かがリスクを引き受けなければならない局面では、まったく別の顔を見せる。

『昭和16年夏の敗戦』は、その問題を極端な状況で見せてくれる本だった。

本の概要と主要な主張

1. 日本には敗戦を予測する能力があった

1941年、総力戦研究所には各省庁や軍、民間企業などから若手のエリートが集められた。

彼らは模擬内閣をつくり、日本と英米との戦争をシミュレーションする。

その結果として導き出されたのは、日本が緒戦では一定の成果を上げても、長期戦になれば国力の差によって敗北するという見通しだった。本書が描くシミュレーションは、後の戦争の推移と驚くほど重なる。

だから本書を読んで、「当時の人々には未来が見えていなかった」と単純化することはできない。

少なくとも一部には、かなり正確に現実を見る人間がいた。

2. 問題は情報ではなく、意思決定の構造だった

それでも日本は開戦した。

ここで浮かび上がってくるのは、分析能力の欠如よりも、組織として意思決定する能力の欠如だ。

それぞれの立場では合理性がある。

陸軍には陸軍の事情があり、海軍には海軍の事情があり、政府には政府の事情がある。

しかし、それぞれが自分の組織の論理を守ろうとすると、全体として最も合理的な判断から離れていく。

誰も単独では「戦争をしたい」と決めていないのに、全員の判断を積み重ねると戦争になる。

これが本書の最も不気味な部分だった。

3. 「空気」は責任を曖昧にする

日本的組織では、決定そのものより、決定に至る合意形成に大きな価値が置かれる。

もちろん合意形成は重要だ。

しかし合意を優先しすぎると、

「これは自分が決めた」

と言う人がいなくなる。

Ownershipが薄くなり、「みんなで頑張ろう」という言葉だけが残る。

うまくいっているときには問題にならない。

問題が起きた瞬間に、

「誰が、何を根拠に、このリスクを取ったのか」

がわからなくなる。

戦争という巨大な失敗の背後にも、この構造があったのではないかと思う。

特に残った3つのアイデア

1. 30代は、経験とAmbitionが最もいい形で交わる時期なのかもしれない

総力戦研究所のメンバーの平均年齢は33歳だったとされる。新版の紹介でも「平均年齢三十三歳」の若手エリート集団として説明されている。

ここが妙に印象に残った。

30代というのは、おそらく一つの特殊な時期なのだと思う。

20代ほど経験がないわけではない。

一方で、40代、50代になって組織の既存構造の中で成功体験や立場を積み重ねた人ほど、過去の成功に縛られているわけでもない。

それなりの成功体験があり、現実がどう動くのかもわかり始めている。

それでもまだ、

「今までこうだったから」

より、

「これからどうすべきか」

を優先できる。

ExperienceとAmbitionのバランスが最も良い時期。

総力戦研究所の若手たちが大胆な結論を出せた理由の一部には、彼らの能力だけではなく、この年齢とポジションもあったのではないかと思う。

そして現代の組織でも、本当に未来について考えるのであれば、30代前後の人材に単に分析をさせるだけでは足りない。

彼らの分析を、実際の意思決定に接続する仕組みが必要なのだと思う。

2. 日本の弱点は「何が正しいか」より「何なら合意できるか」を考えてしまうこと

本書を読んで最も現在につながったのがここだった。

日本の組織では、しばしば意思決定の質そのものよりも、

「この決定ならみんなが納得する」

ことが優先される。

海外生活の中でも、これに似た構造を感じることは何度もあった。

誰か一人が明確にOwnershipを持ち、

「この判断は自分がする。そして結果についても自分が責任を持つ」

と言うよりも、

「関係者で話し合いました」

「みんなで頑張りましょう」

という状態になりやすい。

これは協調性という美徳と表裏一体だと思う。

しかし危機においては、合意と意思決定は別物だ。

全員が納得することと、正しい決断をすることは一致しない。

むしろ大きな決断ほど、一部の人が反対している状態で決めなければならないことがある。

本書が描いているのは、極端に言えば、誰も完全には望んでいない結論に、全員の合意形成プロセスによって到達してしまう怖さなのだと思う。

3. リーダーシップとは「定数」と「変数」を間違えないことなのかもしれない

東条英機についての描写も、自分の中のイメージをかなり変えた。

後世から見ると、東条はどうしても「日本を戦争へ導いた人物」として単純化されやすい。

しかし本書を読むと、東条が最初からただ開戦を望む人物として登場したわけではない、という複雑さが見えてくる。

むしろ重要なのは、東条個人の好戦性を論じること以上に、彼が何を変更可能な「変数」と考え、何を動かせない「定数」と考えていたのかではないかと思った。

ドイツとの関係、軍内部の論理、それまで積み重ねてきた政策。

本来なら問い直せるはずの前提まで「もう変えられない」と扱ってしまえば、意思決定の選択肢はどんどん狭くなる。

そして最後には、

「この条件なら戦争しかない」

という結論になる。

しかし、本当はその「条件」自体を変えることこそリーダーの仕事だったのかもしれない。

これは経営でも同じだと思う。

戦略を考えるとき、与えられた制約の中だけで最適解を探すのはマネジメントだ。

一方で、

「その制約は本当に制約なのか」

と問い直すのがリーダーシップなのではないか。

自分の考えがどう変わったか

読む前の自分には、太平洋戦争についてかなり単純なイメージがあった。

軍部が暴走し、合理的な判断ができなくなり、戦争へ進んだ。

もちろんそれ自体が完全に間違いだとは思わない。

ただ、この本を読んだ後は、それだけでは説明として弱いと思うようになった。

もっと怖いのは、そこに優秀な官僚も、分析も、データも、反対意見も存在したことだ。

にもかかわらず、止まらなかった。

つまり、

「優秀な人を集めれば、組織は正しい判断をする」わけではない。

分析の質と意思決定の質は別物だ。

さらに、民主主義に対する自分の見方も少し変わった。

民主主義国家だから戦争を避けられる、という考えにはかなり疑問を感じる。

民主主義は、戦争を防ぐための装置ではない。

選挙や世論を通して、むしろ国民自身が戦争を支持する可能性も当然ある。

1941年当時に、もし開戦を国民投票にかけていたらどうなったのか。

もちろん反実仮想なので断定はできないが、当時の世論やメディア環境を考えれば、開戦支持が多数になった可能性は十分に考えられる。

だから「政府が戦争をした、国民は被害者だった」という構図だけで戦争を記憶することにも違和感が残る。

政治家にも軍にも巨大な責任がある。

しかし同時に、社会やメディア、そしてそれを支持した市民の側にも問いは向けられるべきだと思う。

民主主義の本当の厳しさとは、政治家を選べること以上に、

その結果について、市民も完全な部外者にはなれないこと

なのではないか。


最後に残った問い

読み終えて一番残った問いはこれだった。

正しい分析が目の前に提示されたとき、組織は本当にそれを使って意思決定できるのか。

これは歴史の問いではない。

会社でも国家でも、問題が起きた後には「実は気づいていた人がいた」という話がよく出てくる。

だとすれば、重要なのは優秀な人材を集めることだけでも、データを増やすことだけでもない。

異論を出せる人間がいること。

その異論が権力者まで届くこと。

そして最後には誰かが、

「この判断は自分がする」

と言うこと。

日本が昭和16年の夏にすでに敗戦を予測していたという事実より、自分にはその方がはるかに重く感じられた。


Japan’s Defeat in the Summer of 1941 — When Good Analysis Fails to Become a Decision

Title: Japan’s Defeat in the Summer of 1941
Author: Naoki Inose
Originally Published: 1983
Category: History / Organizational Decision-Making / Leadership
Date Finished: —
Reading Time: —
In One Sentence: A book about how an organization can possess the right people, the right data, and even the right forecast—and still make the wrong decision.

The Book in One Sentence

This is less a book about why Japan lost the Pacific War than about a more disturbing question:

How can intelligent people correctly predict disaster and still fail to prevent it?

Before Japan entered the war, a group of young elites at the Total War Research Institute conducted a simulation and concluded that Japan would ultimately lose. Yet the country went to war anyway.

The failure, then, was not simply a lack of intelligence.

Japan could analyze.

What it could not do was turn analysis into decision.

Why I Read It Now

The book felt surprisingly contemporary.

While reading it, I kept thinking about organizations I have encountered both in Japan and abroad.

One characteristic of Japanese decision-making in particular stood out to me: we often ask not only,

“What is the right decision?”

but,

“What decision can everyone agree to?”

Consensus is valuable. In stable environments, it can be a real organizational strength.

But consensus and decision-making are not the same thing.

In moments of uncertainty, speed, and asymmetric risk, someone eventually has to own the decision.

That ownership is often remarkably thin.

Instead, the language becomes: “We discussed it together,” or “Let’s all work hard.”

The book shows what happens when that tendency is pushed to an extreme.

Overview & Core Arguments

The Total War Research Institute brought together promising younger officials and professionals to simulate a war between Japan and the Western powers.

Their conclusion was grim: Japan might win early battles, but the difference in industrial and economic capacity would eventually make defeat unavoidable.

And yet Japan went to war.

That makes the central problem much more interesting.

It was not simply that Japan lacked information.

Nor was everyone irrational.

Different institutions had their own internal logic. The Army had its constraints. The Navy had its constraints. Government officials had theirs.

Individually, many decisions could be defended.

Collectively, they produced catastrophe.

No single actor necessarily had to say, “I want this war.”

The system could arrive there on its own.

Three Ideas That Stayed With Me

1. Your thirties may be the sweet spot between experience and ambition

One detail fascinated me: the participants at the institute were, on average, around thirty-three years old.

There may be something special about that stage of a career.

By your thirties, you have usually accumulated enough experience to understand how institutions and people actually work.

But you may not yet be so invested in your own past successes that you instinctively defend the existing system.

You have experience without being entirely captured by it.

That may be the ideal balance between experience and ambition.

The lesson for organizations, however, is not simply “listen to young people.”

The deeper issue is whether the organization has a mechanism for converting their unconstrained analysis into real decisions.

Insight without authority changes very little.

2. Japan often optimizes for consensus rather than ownership

This may be the most relevant lesson of the book for me.

Japanese organizations can spend enormous energy asking whether a decision is collectively acceptable.

The question of who actually owns it often comes later.

That model works until a difficult trade-off has to be made.

The correct decision may not be the one everyone supports.

Leadership sometimes means deciding while disagreement still exists.

What makes the book unsettling is that it shows how an organization can reach a destination that few individuals explicitly chose.

Consensus can paradoxically become a mechanism for avoiding responsibility.

3. Leadership means distinguishing constants from variables

The portrayal of Hideki Tojo complicated my previous mental model of him.

It is tempting, in hindsight, to reduce him to the man who took Japan into war.

But the more interesting leadership question is what he treated as fixed.

Relations with Germany. Commitments already made by the military. Institutional expectations. Previous policy choices.

Once enough assumptions are labeled “unchangeable,” the available decision space becomes tiny.

Eventually the leader can say:

“Given these constraints, there is no alternative.”

But perhaps leadership begins one step earlier.

Which of those constraints are actually constraints?

Managers optimize within a set of assumptions.

Leaders sometimes have to challenge the assumptions themselves.

How It Changed My Thinking

Before reading the book, my mental model of Japan’s entry into the Pacific War was relatively simple: the military became dominant, rational judgment collapsed, and the country moved toward a disastrous war.

I still think that contains part of the truth.

But it is no longer sufficient.

What is more frightening is that rational people existed.

The data existed.

Dissent existed.

And the system still failed.

That changes the lesson dramatically.

Putting smart people in a room does not guarantee a smart organization.

Analytical capability and decision-making capability are two different things.

The book also made me reconsider the comforting idea that democracy itself prevents war.

It does not.

Democratic populations can support wars. Elections can produce leaders who pursue them. Public opinion and the media can reinforce escalation rather than restrain it.

Had a referendum on war been held in Japan at the time, we cannot know the result. But it is hardly obvious that the public would have voted for peace.

That leads to an uncomfortable question about responsibility.

Japan’s postwar narrative has understandably emphasized ordinary citizens as victims of an enormously destructive war.

But democratic citizenship also requires something more demanding: citizens cannot always treat political outcomes as something done entirely by “leaders” to “the people.”

Political leaders carry enormous responsibility.

So do institutions and the media.

But citizens are not necessarily outside that system.

Perhaps one of democracy’s harshest principles is this:

We are not only entitled to participate in collective decisions; we also inherit some responsibility for what those decisions produce.

Where I Question the Author

There is a danger in reading the book too neatly as a story about “Japanese organizational culture.”

Consensus-oriented decision-making and ambiguous responsibility clearly matter.

But the road to war also involved military institutions, imperial ambitions, the ongoing war in China, economic sanctions, domestic politics, public opinion, and an international order under extraordinary pressure.

No single organizational explanation is sufficient.

I would also resist a simplistic contrast between rational young analysts and irrational senior leaders.

The young participants had one major advantage: they could analyze without personally carrying the burden of decades of accumulated commitments.

Real leaders could not.

So the takeaway is not that younger people should simply replace older ones.

It is that organizations need ways to bring perspectives that are not yet imprisoned by existing commitments into the rooms where actual authority resides.

Who Should Read It

I would recommend this book not only to readers interested in wartime Japan, but to anyone who makes decisions inside organizations.

Executives.

Managers.

Civil servants.

And perhaps especially people in their thirties who are beginning to notice that the way an institution currently operates is not the only way it could operate.

If you are looking for a comprehensive military history of the Pacific War, this is not that book.

Its real subject is something more universal:

how organizations decide.

The Question I’m Left With

The question that stayed with me is simple:

When the correct analysis is placed in front of an organization, is that organization actually capable of acting on it?

After disasters, we often hear that someone had warned about the risk.

Someone had the data.

Someone saw it coming.

If so, the real challenge is not merely to hire smarter people or collect better information.

Organizations need people who can challenge assumptions.

They need channels that allow uncomfortable conclusions to reach those with authority.

And eventually, someone has to say:

“I am making this decision, and I own the consequences.”

That, more than the fact that Japan’s defeat had effectively been predicted before the war began, may be the most important lesson of this book.
AIで児童教育は悪化するのか

https://www.economist.com/graphic-detail/2026/08/18/does-ai-stop-children-from-learning?giftId=Y2VhZjQyM2MtMDMxMC00MjIyLWIwZTgtZDc4MTJjODkxZjdj&utm_campaign=gifted_article


「宿題を速く終わらせる」だけでは成績が下がる?——データが示す、AI時代の格差は「使い方」で生まれる

学校教育やビジネス現場で「AIを使うべきか、禁止すべきか」という論争はいまだに続いています。しかし、そろそろこの二元論から抜け出す時が来ています。

重要なのは「AIを使うかどうか」ではなく「どう使うか」です。

それを突きつける、非常に興味深い研究データ(2026年6月発表の論文)が示されました。中国の12歳〜18歳の生徒約2万7,000人を対象に、DoubaoやDeepSeekといったAIツールの利用状況と成績を追跡調査した大規模な分析です。

「宿題が満点」の子ほど、試験で惨敗する怪現象

この研究結果で最も衝撃的なのは、「AIを使って宿題の点数が高くなった生徒ほど、本番の試験で成績が暴落している」という事実です。

  • 作業時間の短縮: AIを使った生徒は、宿題1回あたりの時間が平均64分から45分に短縮されました。

  • 宿題の点数向上: 宿題の平均点は18%アップしました。

  • 試験の点数: しかし、いざAIを使えない本番の試験になると、AIを使って宿題の点数を伸ばしていた生徒のスコアは、使っていない生徒より最大20%以上も低いという結果になりました。

本来、宿題の点数と試験の点数は比例するはずです。なぜこのような正反対の現象が起きるのでしょうか?

効率化(ブルーカーペンター的思考)の罠

ここで少し斜めからの見方(うがった見方)をしてみます。

もし「宿題」というものを「与えられた労働/単純作業」と捉え、「いかに省力化して短時間で提出物という成果物を納品するか」というブルーカーペンター的なタスク消化の発想でAIを使うなら、このやり方は「大正解」です。45分で完璧な回答を作成し、宿題の成績も「満点」が取れるからです。

しかし、学校教育における宿題の本質は「回答を提出すること(作業)」ではなく「解く過程で頭を悩ませて知識を定着させること(学習)」にあります。

  • 丸写し(効率化)の代償: AIに答えを出させ、そのままコピペして提出すれば、思考プロセス(試行錯誤・概念の理解)は完全にスキップされます。

  • 本番での露呈: AIという「杖」を奪われた試験会場で、自分で考える体力が一切ついていないことが露呈します。

「宿題を速く終わらせる」という作業の最適化にAIを使った生徒は、短期的には効率化の恩恵を受けますが、中長期的には自分の思考力を削ること(AIペナルティ)になっていたのです。

「パーソナル家庭教師」としてAIを使う子たち

では、AIを使う生徒全員の成績が下がっているのでしょうか? 答えは「NO」です。

AIを使っていても試験の成績を落とさなかった生徒たちも存在します。彼ら・彼女らに共通していたのは、「宿題にかける時間が非利用者と変わらなかった」点です。

彼らは単に答えを検索してコピペするためではなく、「パーソナル家庭教師」としてAIを活用していました。

  • 難しい概念を自分の理解度に合わせて噛み砕いて解説してもらう

  • 自分が解いたプロセスのどこが間違っているのかヒントをもらう

  • 類題を出してもらい、思考力を深める

このように、自分の頭で考え抜くための「足場」としてAIを賢く(Intelligently)使う子は、AIを使わない子と同等か、それ以上の高い学習効果を得ています。

おわりに:「使わせない」ではなく「問いの質」を教える

今回のデータが教えてくれるのは、AIを単なる「作業代行ツール」として使うか、「思考を深める対話相手」として使うかで、人間の成長カーブは真逆になるという事実です。

これは子供の教育だけでなく、ビジネスパーソンにおけるAI活用でも全く同じことが言えるでしょう。

「作業を早く終わらせる」だけの効率化に終始するのか、それとも「自分の思考を拡張する」ために使うのか。AI時代の格差は、ツールそのものではなく、私たちの「使い方の思想」によってすでに広がり始めています。


Agent AIが普及した時代のAgencyの逆襲

生成AIの進化が「Agentic AI(自律型AIエージェント)」のフェーズに突入する中、私はこの時代における「エージェンシー(代理業・中間業者)」の持つ新たな価値について再考させられている。

これまで、高付加価値ビジネスの頂点にはコンサルティングファームが君臨してきた。彼らのアプローチは、徹底的にクライアントサイドに立ち、顧客のコンテキスト(文脈・内部事情)を吸収し、論理と戦略を構築して交渉力を引き上げることにある。しかし、逆説的だが「クライアントのコンテキストをすべて吸収し、論理的最適解を導き出す」というプロセス自体が、Agentic AIが最も得意とする領域である。AIが自社のコンテキストを完全に理解し、24時間戦略を練り上げるようになれば、そこに外部コンサルタントが追加できる付加価値は急速に縮小する。これが、コンサルタンシーがAgentic AIに飲み込まれる最大の理由だ。

一方で、エージェンシーはどうだろうか。サプライ(供給)とデマンド(需要)の中間に立つという彼らのポジションには、Agentic AI時代においても代替困難なユニークなバリューがある。それは経済学でいう「情報の非対称性」を前提とした交渉と合意形成における責任である。

エージェンシーは、双方のコンテキストを完全に開示・共有するわけではない。あえて情報を非対称な状態に保ちながら中間に立ち、双方にとっての「落としどころ」を見つけてディールをまとめる。将来的に、交渉自体はAgent2Agent(AIエージェント間の自動交渉プロトコル)で解決する部分も出てくるだろう。しかし、最終的にクライアントとサプライヤー間で法的・ビジネス的な「合意」を結び、そのディールに責任を持つ主体としては、やはり法人としての別個の存在(中間業者)が必要とされる。

特にB2Bの領域では、直接交渉ではなく間接的なプレーヤーがクッションとして入ることで初めてうまくいくパターンが数多く存在する。これは人間社会の取引コスト(Transaction Cost)を削減するための歴史的メカニズムである。

一方、B2Cの領域では様相が異なる。消費者は自身のコンテキスト(データや嗜好性)を特定のプラットフォームに「ベンダーロックイン」されないことが最重要課題となる。自分が持つコンテキストを、必要に応じて各ベンダーに適切に開示していくコントロール権が求められる。もしその管理がユーザーにとって煩雑であれば、消費者のコンテキスト管理と最適化を専門に行うSaaSが誕生するだろう。ソフトウェアから始まり、やがてそれは月額課金型の「パーソナルAIエージェント(月額エージェント)」へと進化していくかもしれない。

テクノロジーが情報の透明性を極限まで高める時代だからこそ、「完全には共有されない情報」の間に立ち、ディールを成立させるエージェンシーの泥臭い価値が、今まさに再評価されるべきタイミングに来ている。


As the evolution of generative AI enters the "Agentic AI" phase, I find myself reconsidering the emerging value of "agencies" and intermediaries in this new era.

For years, consulting firms have sat at the apex of high-value business services. Their fundamental approach is to stand firmly on the client's side, absorb the client's internal context entirely, and elevate the client's strategic and negotiating power. However, paradoxically, the very act of "absorbing context to derive logical optimums" is exactly what Agentic AI does best. Once an AI fully ingests a company's context and iterates strategies 24/7, the marginal value added by external consultants will rapidly diminish. This, I believe, is why the consultancy model will eventually be devoured by Agentic AI.

On the other hand, what about agencies? By sitting directly between Supply and Demand, intermediaries possess a unique value proposition that is remarkably resilient, even in an Agentic AI world. This value is rooted in what economists call "information asymmetry"—and the responsibility of closing negotiations based on it.

Agencies do not disclose everything to both sides. Instead, they operate within the asymmetry, acting as a buffer to orchestrate deals and find the optimal middle ground. In the near future, we may see Agent-to-Agent (A2A) protocols resolving the mechanical aspects of negotiations. Yet, when it comes to formalizing an agreement between a client and a supplier, a separate corporate entity taking fiduciary and operational responsibility for the deal will still be necessary.

Particularly in B2B markets, there are countless scenarios where indirect players are required to make a deal work. This intermediary layer acts as a critical cushion, historically proven to reduce transactional friction and build trust where direct negotiations stall.

The B2C landscape, however, will face a different dynamic. For consumers, the ultimate priority will be avoiding "vendor lock-in" of their personal context. The ability to appropriately disclose and control one's context across different vendors will become paramount. If managing this becomes too cumbersome, we will likely see the birth of specialized SaaS platforms dedicated to context management. It is highly plausible that these software solutions will quickly evolve into subscription-based "Personal Monthly Agents."

In an era where technology drives absolute transparency, the highly nuanced, often gritty work of agencies—standing between "undisclosed contexts" to close a deal—is exactly what needs to be re-evaluated.

40歳で思う「軸と型」

English follows Japanese

まぁ似たようなことを以前にも書いてたんだけど、どちらかというと、どんな型、どう型を作りこむかというWhatやHowにフォーカスしていた。今回はもっとWhyの方に言及したいと思う。

monnalisasmile.hatenablog.com


40歳という節目を迎え、キャリアやビジネスマンとしての在り方について色々と思うところが出てきた。

落語家の故・立川談志がかつて語っていたことに、「迷った時ほど、基礎や型に立ち戻る」というアプローチがある。(「型があるから型破り、型がなければ形無し」という言葉も有名だ。)これはビジネスの世界でも真理である。結局のところ、迷ったときに立ち戻るべき「自分の軸」がある人間は強い。

では、軸、及び型はどう作られるのか。まず、軸というのは価値観に近いため、これは少し型とは異なるかもしれない。一方で、軸と型はグラデーションで、意思決定の決め手は軸だけとは限らず、その時の型がモノを言うときがある。型は、過去の成功体験と失敗体験から編み出された極めて実践的なルーティーンと仕事の進め方のスタンスだと考えている。

ある意味で、それは「思考停止ができる強さ」とも言える。心理学の研究において、若年層は新しい環境に適応する「流動性知能」が高いが、年齢を重ねると経験やパターン認識に基づく「結晶性知能」が優位になるとされる。ビジネスマンも同じだ。年季が入り、第一線で修羅場をくぐり抜ければ抜けるほど、意識せずとも自分自身の「型」が顕在化し、他者に負けない確固たる軸として確立されてくる。「自分には何もない」と思っていても、経験は必ず型を形成している。

逆に言えば、20代などの若いうちに自分の強みや型を見出せた人間は、幸運である一方で脆弱(vulnerable)でもある。時代が変化した際、その強みが陳腐化するリスクがあるからだ。本当に強いのは、使い込まれた革製品のように、時間の経過とともに型が変化し、いい味を出していく人間である。彼らには、強固な軸がありながらも、環境に合わせて形を変えるフレキシビリティがある。

私も40を超えて、ホワイトカラー不要論が出てきて、激変するテクノロジーとどう向き合うべきかという課題を感じてきた。私が20年近いキャリアで感じている原則は「まず使うこと、そして使い切ること」「潜れるところまで、潜ってみる」「知ったかぶりをしないこと」だ。新しいツールと古い手法のどちらを選ぶかという表面的な議論に終始するのではなく、その裏にある「メカニズム」を深く理解することが重要になる。

ビジネスにおいて何事も不変ではない。変わりゆく環境のなかで「何を変えず、何を適応させていくか」を見極める眼力が必要だ。歳をとれば、どうしても生物学的な適応力は低下する。だからこそ、シニアになればなるほど「変えないこと(=確立された型)」に武器を置かざるを得ない。

しかし、決して悲観することはない。過去のキャリアを通じて「激しい変化に対応し、生き残ってきたという経験そのもの」が、年配者の最強の武器(メタスキル)となるからだ。若くして自らの軸を見出し、宗教的なまでにそこに没入し切れる人間もごく稀に存在するが、それは選ばれた天才の領域であり、我々のような常人が容易に到達できる境地ではない。

40歳からの戦い方は、無理に若者の流動性を模倣することではない。己の「型」を信じ、過去の適応経験をリソースとして、変化のメカニズムを俯瞰することにあるのだ。

I've reached the milestone of 40, and with it, a torrent of thoughts about my career and what it means to be a professional.

Years ago, I wrote about the concept of "Form" (or Kata in Japanese), but my focus then was more on the What and How—what kind of forms, and how to build them. This time, I find myself deeply contemplating the Why.

The late, great Rakugo master Tatekawa Danshi often emphasized a fundamental truth: when you are lost, return to the basics, to your "kata" (form). There is an old Japanese saying that goes, "Only those with a solid form can break the mold; those without form are merely formless." This holds incredibly true in the business world. Ultimately, having an internal "axis" to fall back on in times of doubt is an undeniable strength.

In a way, this is the strength of "thought-stopping"—relying on ingrained intuition rather than burning cognitive energy. Psychological studies on intelligence highlight that while youth is characterized by "fluid intelligence" (the ability to adapt and process new information quickly), aging brings "crystallized intelligence" (the ability to utilize accumulated knowledge and pattern recognition). The same applies to business professionals. The longer your tenure and the more you operate on the front lines, the more your personal "kata" manifests. Even if you believe you have no special talent, your experiences forge an unbeatable axis.

Conversely, those who discover their unique strengths very early in life are undoubtedly lucky, but they may also be vulnerable. If the market shifts, an overly rigid early specialization can shatter. The truly resilient professionals are like well-worn leather: their "kata" evolves and gains character over time. They possess both a solid core and the flexibility to adapt.

How, then, should we approach the relentless wave of new technology? The baseline rule is to use it, and use it to its absolute limits. It is less about choosing between the "new" and the "old," and more about understanding the underlying mechanisms of why those tools exist.

Nothing in business is immutable. In a constantly changing environment, the ultimate test is determining what to change and what to keep constant. As we age, our raw, biological adaptability inevitably decreases. Therefore, we have no choice but to weaponize what we do not change—our established "kata."

However, this is not a disadvantage. The very experience of having successfully adapted to past paradigm shifts becomes the greatest weapon for seasoned professionals. There are, of course, rare individuals who find their ultimate axis in their youth and immerse themselves in it with almost religious fervor. But that is a special realm, a state of grace that ordinary professionals cannot easily reach.

The strategy for navigating your career post-40 is not to mimic the raw fluidity of youth. It is to trust your "kata," leverage your historical experience of adaptation, and master the underlying mechanisms of change.

Cotext管理とQueryable Organization


リード

生成AIの進化を見ていると、つい「どのモデルが一番賢いのか」「どのツールを導入すべきか」という話に引っ張られがちです。しかし、AIエージェントが本当に仕事の中に入り込んでいく時代において、より本質的な問いは別にあります。

AIに、何を見せるのか。
何を覚えさせるのか。
どの知識を、どの順番で、どの粒度で渡すのか。
そして、組織の知識をどれだけqueryableにできるのか。

この「Contextをどう管理するか」こそが、AI時代の新しい競争領域になりつつあります。

近年、Anthropicの“Effective context engineering for AI agents” は、contextをLLMが推論時に参照する有限のトークン集合と位置づけ、context engineeringを「その限られたcontext windowに入れる情報を継続的に選び、維持する技術」と説明しています。 また、“What an AI Agent Harness Actually Does” では、agent harnessの重要な役割として「モデルが何を見るか」「何に触れられるか」「何が残るか」「失敗時に何が起きるか」を決めることが挙げられています。 [anthropic.com] [tyolab.com]

つまり、AIの価値はモデル単体から、モデルを取り巻くharness、context、memory、workflow、feedback loop へと広がっています。


1. なぜContextが重要なのか

AIエージェントは、単に賢いモデルを呼び出せば動くわけではありません。実際の業務では、モデルが正しい判断をするために必要な情報は、ドキュメント、チャット、会議メモ、チケット、コード、データベース、ナレッジベース、個人の暗黙知などに分散しています。

問題は、情報が「存在しているか」ではなく、AIが必要な瞬間に、適切な形で取り出せるかです。

この点で、context engineeringはprompt engineeringの自然な進化形と言えます。prompt engineeringが「どう聞くか」に焦点を当てるのに対し、context engineeringは「モデルに何を見せるか」を設計します。Anthropicは、agentが複数ターン・長時間のタスクを行うようになるほど、system instructions、tools、MCP、external data、message historyなどを含むcontext state全体を管理する必要があると説明しています。 [anthropic.com]

このとき重要になるのが、agent harnessです。モデルは1ターンごとに推論しますが、その前段で「何をcontextに入れるか」を組み立てるのはharnessです。Tyo Labの記事 は、モデル自体が会話全体を“持っている”わけではなく、各ターンでharnessがモデルに見せるcontextを構築していると説明しています。 [tyolab.com]

この意味で、harnessの付加価値は単なるUIやツール連携ではありません。むしろ、contextを選び、圧縮し、保存し、再利用し、失敗から回復するための運用レイヤーにあります。


2. KarpathyのLLM Wiki:継続的に育つ知識運用

この文脈で非常に重要なのが、Andrej Karpathy氏の LLM Wiki です。

Karpathy氏は、多くのLLM + document workflowはRAGに近く、ユーザーがドキュメントをアップロードし、LLMが質問ごとに関連チャンクを検索して回答する形だと説明しています。しかしこの方式では、LLMは毎回、知識をゼロから再発見しており、蓄積が起きにくいという問題があります。 [gist.github.com]

これに対してLLM Wikiの考え方は、LLMがraw sourcesを読み、要約し、概念ページやエンティティページを更新し、矛盾や関連リンクを管理する persistent wiki を維持するというものです。Karpathy氏は、このWikiを「persistent, compounding artifact」と位置づけ、知識が毎回再合成されるのではなく、一度compileされ、継続的に更新されることを重視しています。 [gist.github.com]

この発想は、RAGの限界を補完します。RAGは「必要な情報を探す」仕組みですが、LLM Wikiは「知識を育てる」仕組みです。

LLM Wikiが示していること

  • 知識は、毎回検索するだけでなく、継続的に編集・統合されるべき
  • LLMは単なる回答生成器ではなく、知識ベースのmaintainerになり得る
  • 人間はsource selection、問い、判断、レビューに集中できる
  • LLMは要約、リンク付け、矛盾検知、index更新などのbookkeepingを担える
  • よい回答や分析もWikiに戻すことで、探索そのものが資産化される

Karpathy氏のLLM Wikiは、厳密なファイル仕様というより、AI時代の知識運用パターンです。どのようにraw sourceを扱い、どのようにWikiへ変換し、どのようにquery / ingest / lintを回すかという、継続的なknowledge operationsの考え方を提示しています。 [gist.github.com]


3. Google OKF:知識を交換可能にするファイルフォーマット

一方、Google Cloudが発表した Open Knowledge Format / OKF は、より具体的なファイルフォーマットの標準化に踏み込んでいます。

Google CloudはOKFを、LLM Wiki patternをportableかつinteroperableな形式にformalizeするopen specificationだと説明しています。OKF v0.1では、知識を Markdownファイルのディレクトリ + YAML frontmatter として表現します。 [cloud.google.com]

OKFの設計は非常にシンプルです。

  • just markdown
  • just files
  • just YAML frontmatter

Google Cloudの記事では、OKF document bundleはGitHubでrenderでき、任意のeditorで読め、任意のsearch toolでindexできると説明されています。frontmatterには、type, title, description, resource, tags, timestamp など、queryableにしたい小さな構造化フィールドを置くことが想定されています。 [cloud.google.com]

さらに、OKF specification では、OKFは人間にもagentにも読みやすい知識表現であり、schema registry、central authority、required toolingを必要としない、最小限の仕様として説明されています。 [github.com]

OKFが示していること

  • 知識はMarkdownで人間にも読めるべき
  • frontmatterで最低限のmetadataを持つべき
  • Gitでversion controlできるべき
  • agent、viewer、catalog、search indexが同じbundleを読めるべき
  • 特定のcloud、model、agent frameworkに依存すべきではない

つまりOKFは、知識をどのようなファイル構造・metadataで持てば、複数のagentやツールが再利用できるかを標準化しようとしています。


4. Karpathy LLM WikiとGoogle OKFの違い

この2つは似ていますが、標準化している対象が異なります。

観点 Karpathy LLM Wiki Google OKF
主眼 継続的な知識運用 交換可能な知識フォーマット
標準化対象 workflow / pattern file format / metadata convention
中心概念 persistent, compounding wiki markdown + YAML frontmatter bundle
目的 RAGのような毎回の再発見を避け、知識を育てる 異なるagentやtoolが同じ知識を読めるようにする
人間の役割 sourceを選び、問いを立て、レビューする knowledge bundleを編集・管理・配布できる
LLM / agentの役割 Wikiを維持し、統合し、lintする OKF bundleを生成・消費・indexする
位置づけ knowledge operations pattern interoperability specification

一言で言えば、Karpathyは「知識をどう育てるか」を語り、OKFは「育った知識をどう持ち運べる形にするか」を語っていると言えます。


5. AI-native companyに必要なのは「Queryable Organization」

ここで、Y Combinatorの The Playbook For Building An AI Native Company とつながります。

YC PartnerのDiana Hu氏は、AI-native companyとはAIを単なるtoolではなく、会社が動くoperating systemとして捉えるものだと説明しています。YCの記事では、すべてのworkflow、decision、processが、学習し続けるintelligent layerを通るべきだと述べられています。 [ycombinator.com]

また同記事では、重要なprocessはintelligent closed loopで捉えられるべきだと説明されています。closed loopは情報を捕捉し、intelligent systemへ戻し、processを時間とともに改善します。 [ycombinator.com]

この考え方を組織知に当てはめると、AI-native companyの本質は「AIを導入すること」ではありません。むしろ、組織の知識、意思決定、プロセス、成果、フィードバックをqueryableにすることです。

Queryable Organizationとは何か

私なりに整理すると、queryable organizationとは次のような状態です。

  • 重要な会議、意思決定、issue、成果物が記録されている
  • 記録が人間だけでなくAIにも読める構造になっている
  • knowledgeが部署や個人の頭の中だけに閉じていない
  • agentが必要なcontextを取り出せる
  • 過去の判断、仮説、失敗、成功を再利用できる
  • feedback loopによって、process自体が改善される

これを実現するには、単に「すべてを保存する」だけでは不十分です。保存された情報が、適切なmetadata、link、summary、status、owner、timestampを持ち、agentが探索できる形になっている必要があります。

ここに、Karpathy LLM WikiとOKFの接点があります。

  • LLM Wikiは、知識を継続的に育てる運用を提供する
  • OKFは、その知識をqueryableでportableなファイル形式にする
  • Harnessは、agentが各ターンで何をcontextとして見るかを制御する
  • AI-native companyは、これらをclosed loopとして組織に埋め込む

6. 今後の勝負所:Contextを資産化できるか

AI時代の競争力は、モデルをどれだけ速く導入するかだけでは決まりません。モデルの性能は時間とともにコモディティ化しやすく、差がつきにくくなります。

むしろ差がつくのは、以下のような領域です。

領域 問い
Context management agentに何を見せるのか
Knowledge operations 知識をどう更新・統合・lintするのか
File / metadata standard 知識をどうqueryableに保つのか
Feedback loop 仕事の結果をどう次の改善に戻すのか
Governance 何をsource of truthとし、誰がreviewするのか
Harness context、tools、memory、failure handlingをどう制御するのか

OpenAIの“harness engineering”記事 でも、人間がコードを書くことではなく、環境を設計し、意図を指定し、feedback loopを構築してCodex agentsが信頼性高く働けるようにすることが重要だと説明されています。 これは、AI-nativeな組織運営において、harnessやcontext layerが中心的な設計対象になることを示しています。 [openai.com]


結論

AI時代の本質的な問いは、「どのAIツールを使うか」から「どのように組織のcontextを設計するか」に移っています。

KarpathyのLLM Wikiは、知識を一回限りの検索対象ではなく、継続的に育つWikiとして扱う考え方を示しました。GoogleのOKFは、その知識をMarkdown + YAML frontmatterというシンプルな形式で、agentやツール間で交換可能にする方向性を示しました。そしてYCのAI-native company playbookは、組織そのものをqueryableにし、intelligent closed loopを回すことの重要性を示しています。

これらを合わせると、次のような見取り図が見えてきます。

AI-native organization = Queryable knowledge + Context-aware harness + Closed-loop operations

今後、組織の競争力は、どれだけ多くの情報を持っているかではなく、その情報をどれだけAIが使えるcontextとして構造化し、継続的に改善できるかで決まっていくのではないでしょうか。


参考リンク


Introduction

For the past few years, much of the AI conversation has focused on models: which model is smartest, which one has the largest context window, which one writes the best code, and which one reasons most reliably.

But as AI agents move from demos into real work, the center of gravity is shifting.

The critical question is no longer only: Which model are we using?
It is increasingly: What does the model see, when does it see it, and how does the organization make its knowledge queryable?

This is why context management, agent harnesses, LLM-maintained knowledge bases, and open knowledge formats are becoming so important.

Anthropic describes context as a finite resource for AI agents and defines context engineering as the work of curating and maintaining the information that enters the model’s limited context window during inference. Tyo Lab’s deep dive on agent harnesses similarly argues that the harness decides what the model sees, what it can touch, what survives, and what happens when things go wrong. [anthropic.com] [tyolab.com]

In other words, the product is not just the model. The product is the system around the model: the context, the memory, the tools, the policies, the feedback loops, and the harness that makes the model useful in production.


1. From Prompt Engineering to Context Engineering

Prompt engineering was about asking better questions. Context engineering is about designing what the model is allowed to know at the moment it answers.

That distinction matters because real AI agents do not operate in a single prompt. They run across multiple turns, invoke tools, read files, inspect logs, consume documents, use external systems, and update their working state. Anthropic explains that as agents operate over longer horizons, teams need strategies for managing the entire context state, including system instructions, tools, MCP, external data, and message history. [anthropic.com]

This is where the agent harness becomes strategically important.

A naive agent loop is simple: send context to the model, execute the tool call, append the result, and repeat. But that breaks down quickly. Context windows fill up. Tool outputs become noisy. Similar files confuse the model. Failed actions get lost. The agent repeats itself. Safety boundaries become ambiguous.

The harness exists to manage this complexity. It decides what enters the context, what gets summarized, what gets preserved, what gets retrieved just in time, what tools are available, and how the system recovers from errors. Tyo Lab’s article emphasizes that the model does not literally “have” the conversation; each turn, the harness constructs what the model sees. [tyolab.com]

That means context management is not a peripheral feature. It is one of the core sources of value in any serious AI agent system.


2. Karpathy’s LLM Wiki: Knowledge as a Compounding Artifact

Andrej Karpathy’s LLM Wiki is one of the clearest articulations of this shift.

Karpathy points out that most LLM-and-document workflows look like RAG: upload a set of files, retrieve relevant chunks at query time, and generate an answer. The problem is that the LLM rediscovers knowledge from scratch each time; there is no accumulation. [gist.github.com]

The LLM Wiki pattern proposes something different. Instead of retrieving raw fragments on every query, an LLM incrementally builds and maintains a persistent wiki: a structured, interlinked collection of Markdown files that sits between the user and the raw sources. When new sources arrive, the LLM reads them, extracts key information, updates topic pages, revises entity pages, flags contradictions, and strengthens the evolving synthesis. [gist.github.com]

The key idea is that knowledge becomes a persistent, compounding artifact.

RAG is useful for finding.
An LLM Wiki is useful for remembering, synthesizing, and improving.

Karpathy’s framing also changes the human role. The human does not need to manually maintain every page. The human curates sources, asks better questions, reviews the outputs, and steers the analysis. The LLM does the bookkeeping: summarizing, cross-referencing, filing, updating, and linting the knowledge base. [gist.github.com]

This is not primarily a file format standard. It is a knowledge operations pattern.


3. Google’s Open Knowledge Format: Knowledge as a Portable Format

Google Cloud’s Open Knowledge Format takes the next step.

If Karpathy’s LLM Wiki describes a pattern for continuously operating knowledge, OKF describes a concrete way to represent that knowledge so different tools and agents can consume it.

Google Cloud describes OKF as an open specification that formalizes the LLM-wiki pattern into a portable, interoperable format. OKF v0.1 represents knowledge as a directory of Markdown files with YAML frontmatter. [cloud.google.com]

The design is intentionally simple:

  • just Markdown
  • just files
  • just YAML frontmatter

The frontmatter can carry structured fields such as type, title, description, resource, tags, and timestamp, while the Markdown body carries the human-readable and agent-readable content. [cloud.google.com]

The OKF specification describes the format as minimal, human- and agent-friendly, and not dependent on a schema registry, central authority, or required tooling. It is designed so that knowledge can be authored by people, generated by agents, exchanged across organizations, and consumed by both. [github.com]

This is important because most organizational knowledge is fragmented. It lives in metadata catalogs, wikis, shared drives, code comments, notebook cells, and the heads of experienced employees. Google Cloud explicitly identifies this fragmentation as a problem for agents that need the right context to answer questions or take action. [cloud.google.com]

OKF’s bet is that the missing layer is not another proprietary knowledge platform. It is a portable knowledge format.


4. LLM Wiki vs. OKF: Two Different Kinds of Standardization

Karpathy’s LLM Wiki and Google’s OKF are closely related, but they standardize different things.

Dimension Karpathy LLM Wiki Google OKF
What it standardizes Knowledge operations pattern Knowledge file format
Primary question How should knowledge compound over time? How should knowledge be represented so agents can exchange it?
Core artifact Persistent LLM-maintained wiki Markdown + YAML frontmatter bundle
Main value Avoid re-deriving knowledge from raw sources every time Make knowledge portable and interoperable
Human role Curate sources, ask questions, review synthesis Author, inspect, version, and distribute bundles
Agent role Ingest, update, cross-link, lint, synthesize Generate, consume, index, visualize, traverse
Strategic meaning Knowledge becomes operational memory Knowledge becomes queryable infrastructure

Put simply:

Karpathy standardizes how knowledge is operated.
Google OKF standardizes how knowledge is packaged.

Both matter. The first helps organizations make knowledge compound. The second helps that knowledge travel across agents, tools, and teams.


5. The AI-Native Company Is a Queryable Company

This connects directly to Y Combinator’s The Playbook For Building An AI Native Company.

In that Startup School episode, YC Partner Diana Hu argues that AI should not be treated merely as a tool a company uses. Instead, AI should be the operating system the company runs on. Every workflow, decision, and process should flow through an intelligent layer that is constantly learning and improving. [ycombinator.com]

The same YC piece emphasizes that every important process should be captured by an intelligent closed loop: a system that captures information, feeds it back into an intelligent system, and improves the process over time. [ycombinator.com]

That is a powerful frame.

An AI-native company is not simply a company where employees use chatbots. It is a company where the operating knowledge of the business is captured, structured, queried, and improved through intelligent loops.

In practical terms, this means the organization needs to become queryable.

A queryable organization is one where:

  • decisions are captured
  • documents are structured
  • meeting outputs are reusable
  • metrics have definitions
  • owners and timestamps are explicit
  • processes leave traces
  • feedback loops are visible
  • agents can retrieve the right context without asking ten people

This is where the LLM Wiki, OKF, and agent harness come together.

The LLM Wiki gives knowledge a way to compound.
OKF gives knowledge a portable structure.
The harness decides which knowledge becomes context at each step.
The AI-native company closes the loop so the system improves over time.


6. The Real Moat: Queryable Context

Model capability will continue to improve. But as models become more capable and widely available, the durable advantage will shift toward the systems that surround them.

The winners will not simply be the organizations with the most documents. They will be the organizations that can turn documents, decisions, workflows, and feedback into queryable context.

OpenAI’s harness engineering article describes a shift where human work becomes less about manually writing code and more about designing environments, specifying intent, and building feedback loops that allow Codex agents to work reliably. That same pattern applies beyond software engineering. The highest-leverage human work increasingly becomes designing the operating environment in which agents can succeed. [openai.com]

The question for every organization is therefore not simply:

“How do we adopt AI?”

It is:

“How do we make our organization legible to AI?”

That means building systems where knowledge is captured, structured, linked, versioned, reviewed, and made available as context.


Conclusion

The next phase of AI will not be defined only by better models. It will be defined by better context systems.

Karpathy’s LLM Wiki shows how knowledge can become a persistent, compounding artifact instead of being re-derived from raw documents on every query. Google’s OKF shows how that knowledge can be represented as a portable, interoperable bundle of Markdown files with YAML frontmatter. YC’s AI-native company playbook shows why the broader organizational goal is to make the company itself queryable through intelligent closed loops.

The emerging architecture is clear:

AI-native organization = queryable knowledge + context-aware harness + closed-loop operations

The companies that learn how to manage context will get more out of every model, every agent, and every workflow.

In the AI-native era, the question is not just who has the best model.
It is who has the most usable context.